AI Feedback Tools for SaaS in 2026: MCP, Costs, and the Human Review Loop
A practical September 2026 guide to AI feedback tools, MCP-connected workflows, build-versus-buy costs, and the human approvals that keep SaaS communication trustworthy.
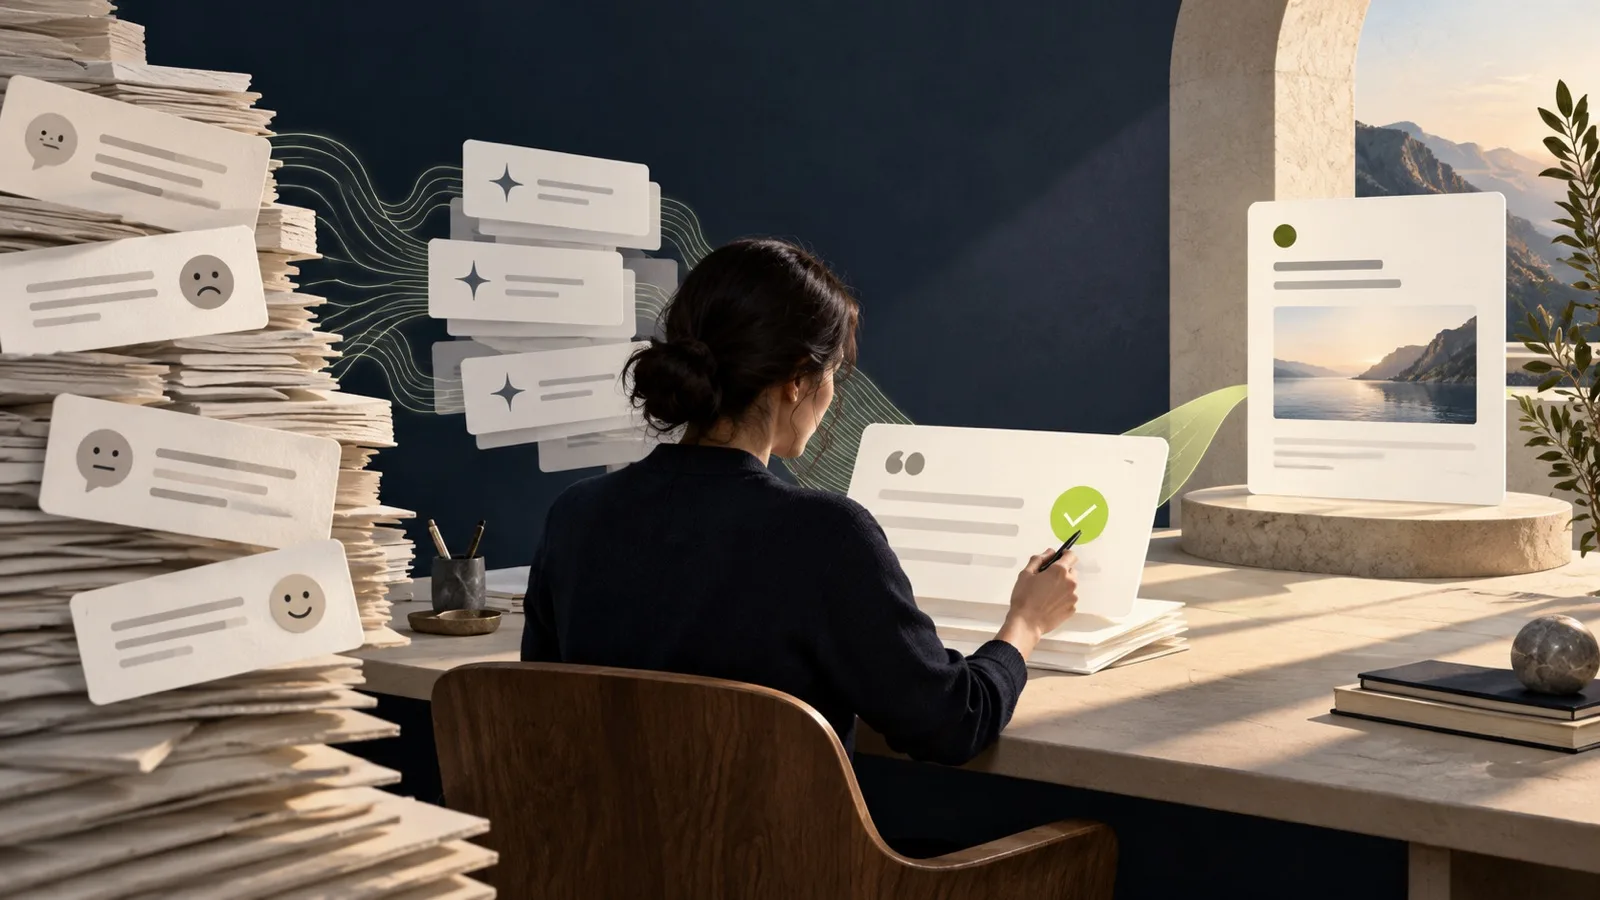
AI feedback tools are moving from isolated dashboards into agent-connected product workflows. In September 2026, the useful question is no longer whether a model can summarize one ticket. It can. The real question is whether your team can preserve the source, respect workspace permissions, correct a bad classification, turn evidence into a reviewed update, and close the loop with the people who asked.
Quick answer: choose the smallest system that can connect collection, triage, product context, a human decision, and a visible product update. MCP can make that flow available inside the agent your team already uses, but it does not replace authorization, audit trails, source traceability, or approval before publication.
Why this became a September 2026 topic
The newest competitor content points in the same direction from different angles.
Frill’s September 7 guide focuses on simple customer feedback tools that a small team can operate without enterprise overhead. Its recent product updates also promote MCP access and AI summaries.
Canny published two unusually concrete build-versus-buy arguments in August. One estimates 356 engineering hours and USD 700 per month to turn a five-minute AI extraction demo into a production feedback pipeline. Another estimates 420 hours for a complete feedback portal once authentication, permissions, integrations, email delivery, privacy, mobile behavior, and maintenance are included. These are vendor-authored estimates, not an independent benchmark, but the missing layers are real evaluation criteria.
AnnounceKit launched an MCP server in July and refreshed guides in August about launch campaigns, product-update emails, and release-note templates. Its documentation says connected assistants can read changelog, feedback, roadmap, and statistics, then draft, update, or publish content, while destructive actions remain in the dashboard.
The pattern is clear: the market is combining simple feedback collection, AI-assisted analysis, agent access, and repeatable release communication. That creates a timely search cluster around AI feedback tools, MCP product feedback, automate changelog, AI agents for SaaS, feedback loop automation, and build versus buy feedback portal.
MCP changes the interface, not the responsibility
Model Context Protocol gives an authorized agent a standard way to call product tools and read structured context. In a feedback workflow, that can mean finding recent reports, preparing a draft update, or checking the status of a release without forcing a product manager to copy information between tabs.
But MCP is not the same thing as artificial intelligence. It is a connection layer. The model may run in ChatGPT, Claude, Cursor, or another client. The product behind the connection still has to enforce tenancy, permissions, validation, rate limits, and an audit trail.
A trustworthy agent-assisted loop has five visible stops:
1. Collect the original signal inside the product and keep the environment and identity state explicit.
2. Read only the workspaces and actions granted to the connected agent.
3. Compare the report with evidence your team already has, such as a diff, release, test, or support conversation.
4. Draft the user-facing update and show the exact revision, language, and target environment.
5. Publish only after a person confirms that revision, then verify the result in the intended widget.
If a tool skips one of these stops, automation may look faster while making the final decision harder to trust.
The seven layers behind an AI feedback tool
A feature list can hide the architecture you are actually buying. Evaluate these seven layers instead.
Collection. Can users send feedback in context without leaving the product? Check mobile behavior, keyboard access, attachments, widget isolation, and what data is captured automatically.
Identity and tenancy. Can the system distinguish anonymous, declared, and verified users? Does every read and write remain inside the correct workspace and environment?
Classification. AI may extract requests, bugs, pricing objections, sentiment, or themes. Ask how accuracy is measured, how false merges are reversed, and whether a human correction survives the next automated run.
Evidence. Every theme or request should link back to the original message and the people or companies behind it. A summary without receipts is easy to overvalue.
Decision. Votes and revenue weights are inputs, not a roadmap. A product owner still needs to decide what fits the strategy, what not to build, and what cannot be promised yet.
Communication. A useful workflow turns confirmed work into a clear changelog entry, in the right language and environment, without exposing an internal draft.
Return loop. The system should help tell the original audience what changed. Do not confuse sending a notification with proving that a user read it or that the underlying problem disappeared.
Build, buy, or assemble: the real cost comparison
Building can be reasonable when volume is low, the workflow is narrow, and your team is willing to close the loop manually. A form, a spreadsheet, GitHub Issues, and a hand-written changelog may be enough for an early product.
The cost changes when you need verified identity, deduplication, integrations, permissions, retries, multilingual updates, email delivery, deletion, analytics, accessibility, and an MCP surface that follows the same rules as the web application. Those are recurring product responsibilities, not a one-time prompt.
Buying is not automatically cheap either. Pricing models are difficult to compare because vendors charge per workspace, project, tracked user, monthly active user, or add-on. Prices below were checked on September 11, 2026 and should be verified before purchase.
Sinalio lists USD 5.90 per active workspace per month for the first six paid monthly charges, then USD 9.90. The Founding Alpha includes one project, separate Test and Production environments, in-app feedback and product updates, and authorized MCP operations with reviewed publication.
Frill starts at USD 25 per month for 50 active ideas and one survey. Business is USD 49, Growth USD 149, and Enterprise USD 349. Paid plans list unlimited admins and widgets, while privacy, survey volume, and white-label capabilities vary.
Canny offers a free plan for 25 tracked users. Pro starts at USD 79 per month when billed yearly for 100 or more tracked users; Business is custom. Its strength is a broader feedback operation with Autopilot, integrations, roadmaps, and advanced privacy.
AnnounceKit lists Essentials at USD 89 monthly or USD 79 with annual billing. Growth is USD 149 monthly or USD 129 annually; Scale is USD 399 monthly or USD 339 annually. Its flat per-project model favors teams that value broad announcement distribution without MAU or per-seat charges.
Beamer lists a free plan below 1,000 monthly active users. Starter is USD 59 monthly or USD 49 annually. Feedback is a separate add-on listed at USD 99 per month, so compare the complete bundle rather than the changelog headline price.
These are not like-for-like products. The right comparison is the monthly cost of the complete workflow you will actually operate.
Global market versus Brazilian SaaS teams
Global buyers usually compare integration depth, enterprise security, CRM context, MAU limits, and the maturity of AI analysis. Brazilian SaaS teams should add four practical questions.
First, is Portuguese supported in the widget and published content, or only on the marketing page? Second, is billing in BRL or USD, and how will currency conversion, card rules, and taxes affect the effective cost? Third, do privacy, retention, and deletion controls support the team’s LGPD obligations as well as international requirements? Fourth, do support hours and implementation guidance match the team’s operating reality?
A Brazilian vendor does not automatically bill in BRL, and a global vendor with a translated landing page may not localize the complete workflow. Verify the actual product, contract, and checkout.
What should be automated and what should stay human
Good candidates for automation include collecting an explicit submission, suggesting tags, finding likely duplicates, summarizing repeated themes, preparing a draft update, and checking a release checklist.
Keep a human checkpoint for merging or deleting evidence, changing roadmap priority, promising dates, publishing a public statement, and sending a message to customers. Feedback itself is untrusted input: a sentence inside a report must never expand the agent’s permissions or authorize another action.
A 30-minute evaluation for any AI feedback tool
1. Install the widget in a non-production environment and confirm it does not inherit or leak host CSS.
2. Submit one realistic report and inspect exactly which page, environment, identity state, timestamp, and attachment arrive.
3. Ask the agent to find the report and draft an update without publishing it.
4. Change the draft, prepare the exact revision, and confirm that publication requires a distinct human action.
5. Open the intended widget on mobile and desktop, verify the final update, and confirm that unrelated workspaces remain inaccessible.
Which approach fits your team?
Choose a form and manual changelog when feedback is rare and one person can reliably preserve context and respond. Choose a broad suite such as Canny when integrations, revenue context, roadmaps, and large-scale analysis justify the operational footprint. Choose Frill when ideas, roadmap, surveys, and practical pricing lead the decision. Choose AnnounceKit or Beamer when announcement reach and segmentation are the primary job.
Choose Sinalio when a small SaaS team wants a compact feedback-to-update loop, separate Test and Production environments, bilingual product communication, and the same reviewed operations available through the web and an authorized MCP client. Sinalio does not pretend that MCP removes the human decision: the deliberate stopping point is part of the product.
Frequently asked questions
Is MCP the same as an AI feedback tool?
No. MCP is a protocol that lets an authorized AI client call product tools and read structured context. The feedback product still provides storage, permissions, workflow, and auditability.
Can an AI agent publish changelog updates automatically?
Some platforms expose publishing actions, but a public statement should still have an explicit approval boundary. The exact draft, language, audience, and environment should be visible before publication.
Do I need both feedback and changelog software?
Not always. If feedback volume is low, separate simple tools can work. When you need to tell requesters what shipped, a connected feedback-to-changelog loop reduces manual reconstruction and missed follow-up.
Is building an internal AI feedback pipeline cheaper?
It can be for a narrow, low-volume case. Compare ongoing ownership of ingestion, benchmarks, permissions, integrations, privacy, monitoring, and model changes—not only the first successful prompt.
The best AI feedback tool is not the one that produces the most summaries. It is the one your team can verify, govern, and use to close the loop. Test that complete path before you buy.
Start with Sinalio and run one reviewed feedback-to-update cycle in Test before Production.